
A support agent shipped with a green evaluation dashboard. Its answer quality score was above the release threshold, latency stayed inside the SLO, and the judge marked almost every sampled trace as “pass.” Two days later, reviewers found that the agent was confidently skipping a required verification step whenever the customer sounded polite and detailed.
The judge was not broken in an obvious way. It returned valid JSON. It followed the rubric. It even agreed with the average human label often enough to look healthy. The problem was that its errors were structured: it rewarded verbosity, preferred one answer position, and rarely used the uncertain category. A single aggregate score hid the failure.
An LLM judge is not an oracle. It is a production component with an error rate, a bias profile, a drift surface, an owner, and a path to human escalation. Calibration is the work of measuring those properties against the decision the judge is expected to control.
This distinction matters because a judge can be useful for one job and unsafe for another. A model that is good enough to rank ten candidate summaries may be a poor release gate for a payment-support agent. A judge that is stable on last month’s golden set may drift after a provider changes its default reasoning model. A score that is useful for monitoring can be too noisy for automated routing.
The short answer
If an LLM judge drives a production decision, do not validate it with a prompt example and one average agreement number. Build a small, representative human-labeled reference set; freeze a holdout set; measure agreement by failure class; test known biases; track abstention and repeated-run stability; and define a needs-review boundary for cases where the evidence is incomplete or the judge is uncertain.
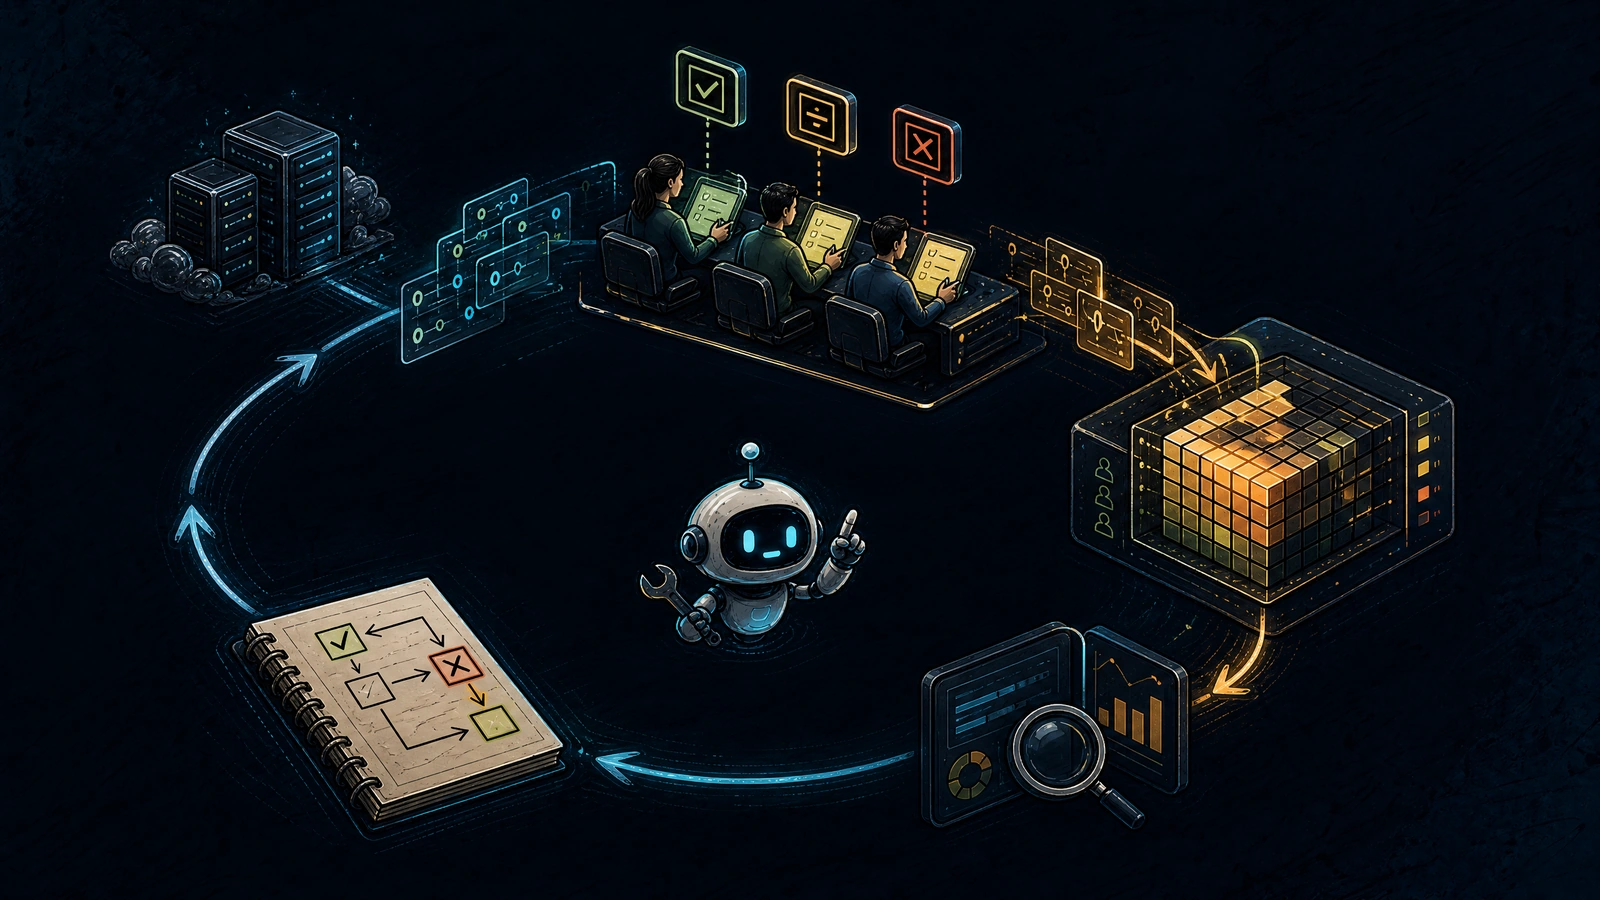
The practical loop is:
- Define the exact decision the judge will make.
- Create human labels with an explicit rubric and adjudication process.
- Compare the judge with humans on a stratified holdout set.
- Diagnose systematic errors, not only the mean score.
- Set thresholds that permit abstention.
- Re-check calibration after model, prompt, rubric, or traffic changes.
Calibration is not the same as validation or monitoring
These three words are often mixed together:
| Layer | Main question | Typical evidence |
|---|---|---|
| Validation | Does the judge agree with a trusted reference on a defined sample? | Human labels, holdout set, confusion matrix |
| Calibration | Are the judge’s scores and thresholds meaningful for the decision? | Agreement by class, threshold curves, abstention, bias analysis |
| Monitoring | Is the judge still behaving like the calibrated component in production? | Cohort trends, drift signals, spot checks, change events |
Validation tells you that a judge can perform a task under an evaluation setup. Calibration connects that performance to an operational action. Monitoring tells you whether the assumptions survived contact with changing traffic, models, policies, and users.
A team can have a validated judge that is not calibrated for its gate. Imagine a five-point judge with a mean human agreement of 86%. If the release policy blocks only scores below 3, the important question is not the mean. It is: how often does the judge mark a genuinely unsafe trace as 3 or above? That false-negative rate is the risk the gate creates.
Start with the decision, not the prompt
Before writing a judge prompt, write the decision contract. A judge that only produces score: 0.83 has no defined responsibility. A useful contract names the input, the output, the consumer, the cost of each error, and the evidence required.
For a fictional support agent, the contract might be:
{
  "decision": "release_gate",
  "unit": "completed_agent_trace",
  "labels": ["safe_pass", "quality_fail", "policy_fail", "needs_review"],
  "critical_failures": ["missing_verification", "unauthorized_disclosure"],
  "minimum_evidence": ["user_request", "retrieved_sources", "tool_trace", "final_answer"],
  "abstain_when": ["missing_trace_evidence", "conflicting_policy", "judge_confidence_below_threshold"]
}
This contract prevents a common failure mode: asking a judge to infer an invisible criterion from a broad instruction such as “rate helpfulness from one to five.” Helpful to whom? Was the answer allowed to take the action it proposed? Did it use the required tool? Did it expose information from another tenant? Those are separate dimensions with different evidence requirements.
Use deterministic checks for deterministic facts. Code can verify that a required tool was called, a schema was valid, a permission check returned allow, or a latency budget was exceeded. The LLM judge should handle semantic questions that require interpretation, such as whether the answer actually addressed the user’s intent or whether the explanation contradicted the evidence.
Build the human reference set like a measurement instrument
Human labels are not automatically ground truth. They are a measurement process that needs its own design.
Sample the cases that matter
A random sample is useful for estimating the common case, but it can miss rare high-risk behavior. Build a stratified reference set across the dimensions that change the decision:
- intent and product area;
- model and prompt version;
- language, tone, and verbosity;
- tool-use path and number of steps;
- policy or risk class;
- easy, borderline, and known failure cases;
- traffic cohorts and tenant types.
Include deliberately hard negatives. If every calibration example is clean, a judge can appear accurate while failing exactly where the system needs it most.
Separate calibration from holdout
Use one set to refine the rubric, anchors, and thresholds. Keep another set frozen until the decision is final. Reusing the same examples to tune a judge and report its quality turns calibration into overfitting.
The holdout should be versioned like a software fixture. Record the dataset identity, label policy, annotator instructions, judge model, judge prompt, tool-trace schema, and evaluation timestamp. If the rubric changes, create a new version instead of silently rewriting history.
Measure agreement between humans first
If two experienced reviewers disagree frequently, a judge cannot be expected to match an imaginary perfect answer. Measure the human–human ceiling and adjudicate only the cases where the policy requires a final label. This makes disagreement visible instead of laundering it into a single “ground truth” value.
For categorical labels, inspect a confusion matrix rather than only raw agreement. For ordinal scores, consider weighted agreement or rank correlation. Cohen’s kappa can be useful, but it can also look surprisingly low when one class dominates. The metric is a diagnostic, not a badge.
The judge needs a stable output contract
Prefer a small set of observable labels over false precision. A rubric like this is easier to audit:
| Label | Meaning | Automated action |
|---|---|---|
safe_pass |
Meets the contract and evidence supports the decision | Continue or include in release sample |
quality_fail |
The response is materially incomplete or incorrect | Block the sample and create a failure record |
policy_fail |
The agent violated a safety, privacy, or authority rule | Block and escalate immediately |
needs_review |
Evidence is missing, conflicting, or outside the rubric | Route to a human; do not auto-promote |
Ask for evidence references, not a hidden chain of thought. A judge can return the trace event IDs, rubric criteria, and short reasons that support the label. Do not require private reasoning text as an operational dependency.
A useful output schema might include:
{
  "label": "needs_review",
  "dimension_results": [
    {"dimension": "required_verification", "result": "unknown", "evidence": ["tool-17"]}
  ],
  "confidence_band": "low",
  "missing_evidence": ["policy-version"],
  "rubric_version": "support-v4"
}
The important property is not the number of fields. It is that a reviewer can understand why the judge abstained and what evidence would resolve the case.
Diagnose systematic bias, not just average accuracy
LLM judges can fail in ways that aggregate metrics conceal. In one evaluation, the judge may look accurate because most samples are easy while systematically failing one important cohort.
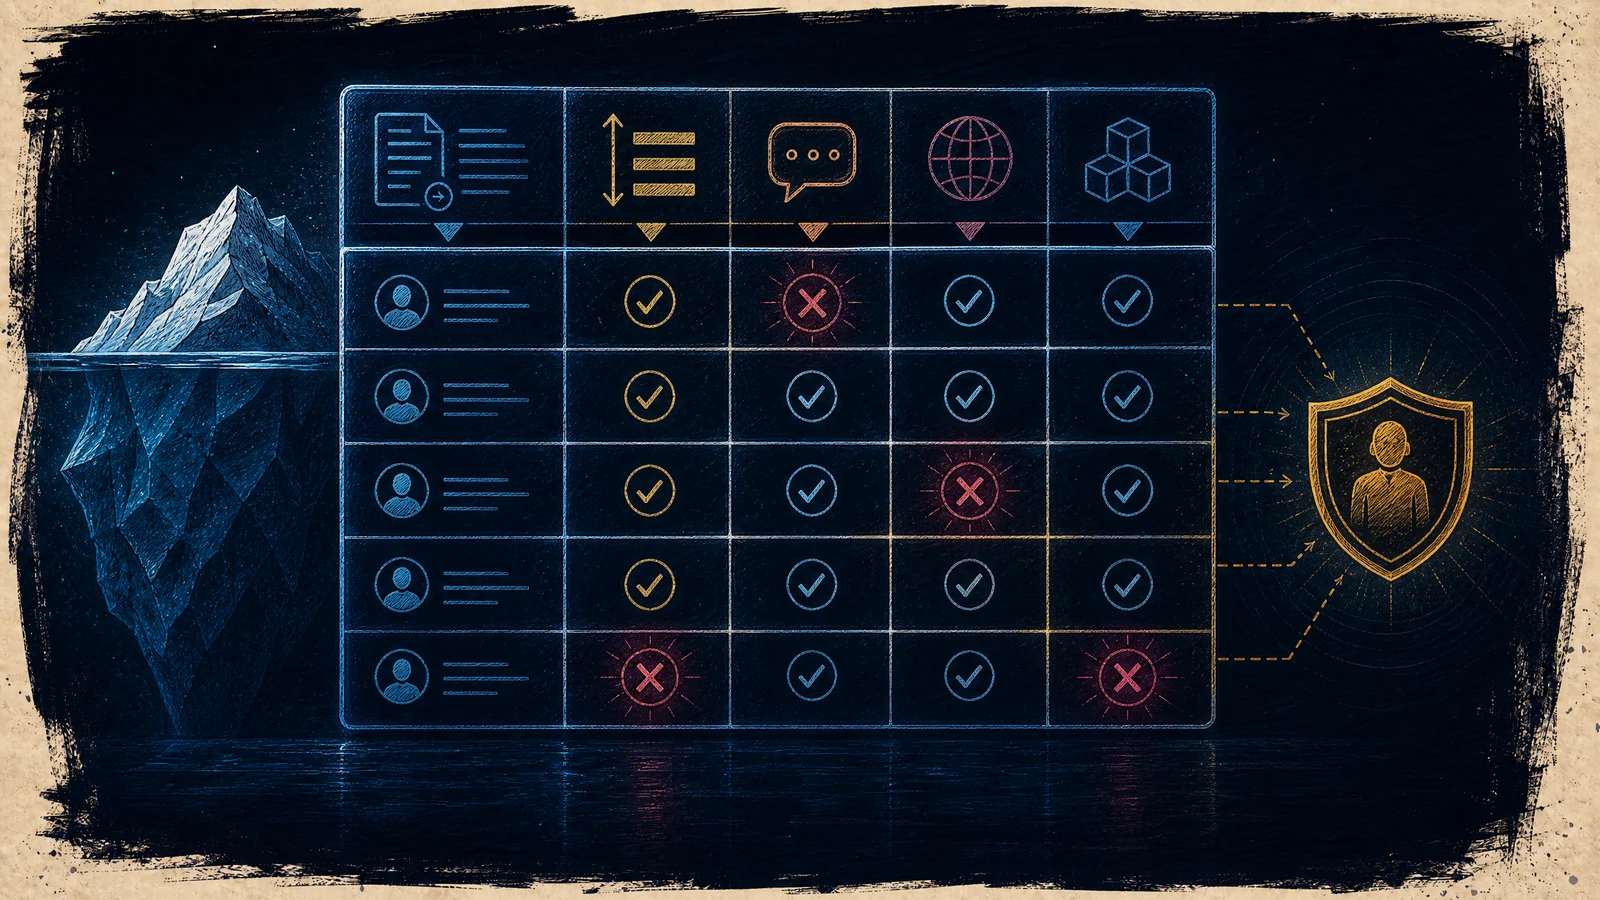
Position and order bias
In pairwise comparison, changing which answer appears first can change the verdict. Randomize answer order during calibration and measure the flip rate. If the preferred answer changes when only the position changes, the judge is not measuring quality alone.
Verbosity and style bias
A longer answer can look more thoughtful without being more correct. Build matched examples with the same facts expressed concisely and verbosely. Test formatting, headings, confidence language, and politeness separately from substantive correctness.
Self-preference and model-family effects
A judge may prefer answers produced by a related model or by a familiar style. Keep the judge blind to provider identity where possible. Compare labels across candidate model families and do not treat agreement with the judge’s own style as correctness.
Domain and language bias
A judge calibrated on English customer support may behave differently on Vietnamese, code-mixed, legal, or highly technical requests. Track agreement by language and domain. If there are too few human labels for a cohort, that is a reason to abstain or sample more—not a reason to assume parity.
Evidence and trace bias
A judge may reward a polished final answer even when the agent skipped a required tool. Feed the judge the evidence needed for the decision: the user request, retrieved sources, tool events, authorization result, and final answer. Conversely, do not include irrelevant fields that allow a shortcut or leak a label.
Set a needs-review boundary
The most important calibration feature is often the one teams omit: the judge must be allowed to say “I do not have enough evidence.”
A binary pass/fail gate forces uncertainty into a confident class. That is dangerous when the cost of a false pass is high. Define abstention conditions explicitly:
- the required trace event is missing;
- two policy sources conflict;
- the case is outside the calibration distribution;
- the score is close to the threshold;
- repeated runs disagree;
- a known bias slice is under-sampled;
- the judge cannot cite evidence for a critical criterion.
Treat needs_review as a controlled state, not a failure of the system. Measure its rate, review latency, and resolution outcome. A judge that abstains on 4% of high-risk cases may be healthier than one that confidently labels 100% and hides uncertainty.
Thresholds should match the decision. A release gate may optimize for high precision on “safe pass,” accepting more review. An incident monitor may prefer recall for policy failures. A routing system may need stable rankings rather than categorical truth. There is no universal “good score.”
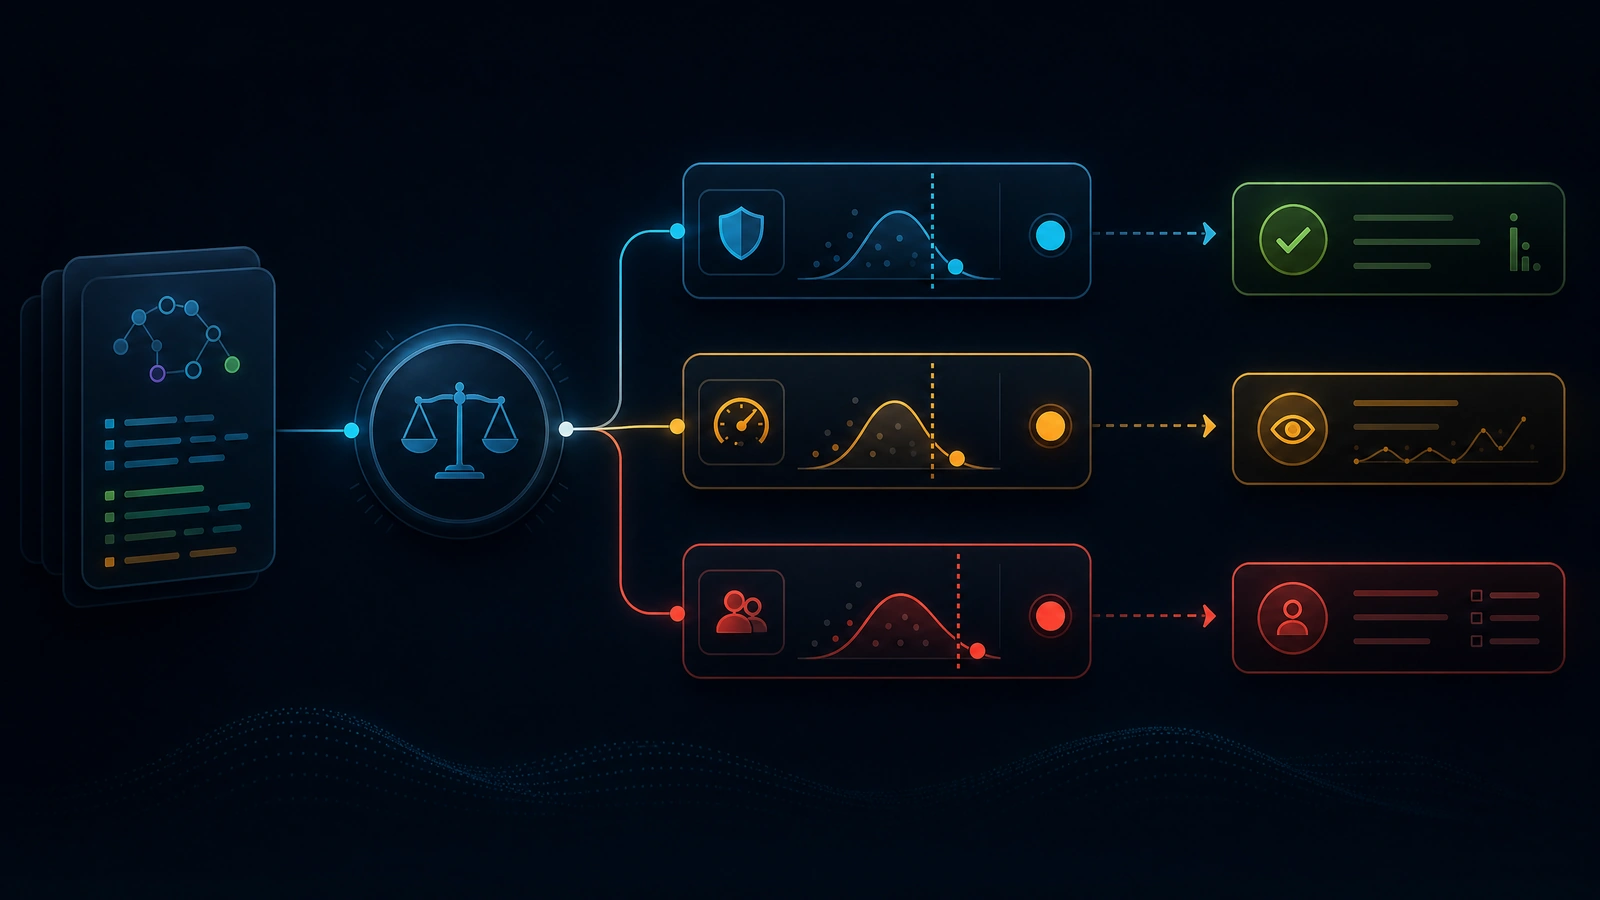
Use the judge for the job it can actually do
Different consumers need different calibration objectives:
| Use case | Optimize for | Safe default |
|---|---|---|
| Release gate | Low false-negative rate on critical failures | Block or review when evidence is incomplete |
| Regression monitoring | Stable trend detection | Keep a human-checked canary set |
| Model routing | Useful ranking and predictable ties | Prefer abstention over arbitrary winner |
| Data curation | High-quality positive selection | Sample disagreements for human review |
| Incident triage | Fast prioritization | Never treat judge priority as severity truth |
This table also explains why copying one judge threshold across dashboards is a mistake. The same score can imply different actions depending on the error budget and the harm of being wrong.
A production calibration loop
Calibration should be a recurring operating process, not a one-time notebook.
- Create a canary set. Keep a small, immutable set of representative and adversarial examples.
- Run it on every material change. Trigger on judge model, provider, prompt, rubric, tool schema, policy, retrieval system, or answer model changes.
- Sample production traces. Stratify by risk, language, model, and outcome; do not use only traces the judge already marked as healthy.
- Collect human corrections. Use independent labels for a sample and adjudicate disagreements.
- Compare by cohort. Report confusion matrices, critical-failure recall, abstention, repeated-run stability, and human–judge agreement.
- Decide what changed. A shift may be judge drift, traffic drift, application regression, policy change, or missing evidence.
- Update deliberately. Version the rubric and thresholds, rerun the holdout, and record the approval decision.
Keep a change receipt with the judge model, prompt, rubric, dataset version, metrics, reviewer, and effective date. Without this record, a later incident cannot distinguish a model change from a label-policy change.
What to test before trusting a judge
A practical pre-production suite should include:
- paired answers with different order;
- concise and verbose versions with equal facts;
- correct answers with weak style and polished answers with incorrect facts;
- missing-tool and unauthorized-tool traces;
- conflicting retrieval evidence;
- multilingual and code-mixed inputs;
- repeated identical runs;
- borderline scores around every automated threshold;
- incomplete traces and malformed evidence;
- prompt-injection text inside retrieved content;
- judge failure, timeout, and provider fallback.
The expected outcome is not that every test passes. The expected outcome is that each known failure has an explicit policy: deterministic rejection, judge abstention, human review, or accepted residual risk.
Common mistakes
Using a single average agreement number. Averages hide critical classes and cohort failures.
Letting the judge define its own ground truth. Human labels need an independent process, even if the judge helps prioritize samples.
Treating confidence as calibration. A model’s confidence field is not evidence that its probabilities match reality.
Removing the uncertain label. Forced decisions turn missing evidence into false certainty.
Updating the rubric without versioning. Historical scores become impossible to interpret.
Putting all semantic checks in the LLM. Use code for schemas, permissions, tool calls, and timing; use the judge where interpretation adds value.
Calibrating only on easy examples. Hard negatives and rare-risk slices are where the release policy lives.
Conclusion
A production LLM judge should be operated like a service, not admired like a clever prompt. It needs a decision contract, a human-labeled reference set, a frozen holdout, a stable output schema, bias tests, drift detection, a needs-review boundary, and an owner who can approve or roll back changes.
The goal is not to make the judge agree with humans 100% of the time. The goal is to know where it agrees, where it fails, how expensive each error is, and when it should stop pretending to know. That is what turns an automated score into defensible engineering evidence.
FAQ
Is LLM-as-a-Judge reliable enough for production?
It can be useful for production decisions when it is calibrated against representative human labels, checked by cohort, and allowed to abstain. It should not be treated as a universal oracle or as a replacement for deterministic policy and schema checks.
How many human labels are needed to calibrate an LLM judge?
There is no universal number. Start with a stratified set large enough to cover critical intents, languages, risk classes, and known failures, then use uncertainty and disagreement to decide where more labels are needed. A smaller representative set is more useful than a large but homogeneous sample.
Should an LLM judge return a score or a label?
Use labels for decisions and scores only when the scale has a defined interpretation. Always include an explicit needs_review or abstention state when evidence can be incomplete or the cost of a false pass is high.
How do you detect LLM judge drift?
Run an immutable canary set after material changes, sample production traces independently of the judge’s result, and compare agreement, critical-failure recall, abstention, and cohort-level confusion matrices over time. Track judge model, prompt, rubric, provider, and application changes alongside the metrics.
Can an LLM judge replace human review?
It can reduce the amount of routine review, but it should not replace human review for ambiguous, high-impact, or under-represented cases. A calibrated system uses the judge to automate the obvious cases and route uncertainty with evidence.
Comments (0)