
A normal API has a fairly clear contract. It receives a request, returns a response, and exposes familiar signals such as error rate, latency, and availability. An AI agent is different. It may call several models, retrieve documents, retry a tool, ask a clarification question, and still produce an answer that looks plausible.
That makes “the request returned 200” a poor definition of reliability. An agent can be fast and wrong, accurate and too expensive, or successful while violating a policy boundary. A useful SLO must represent the work the user actually cares about.
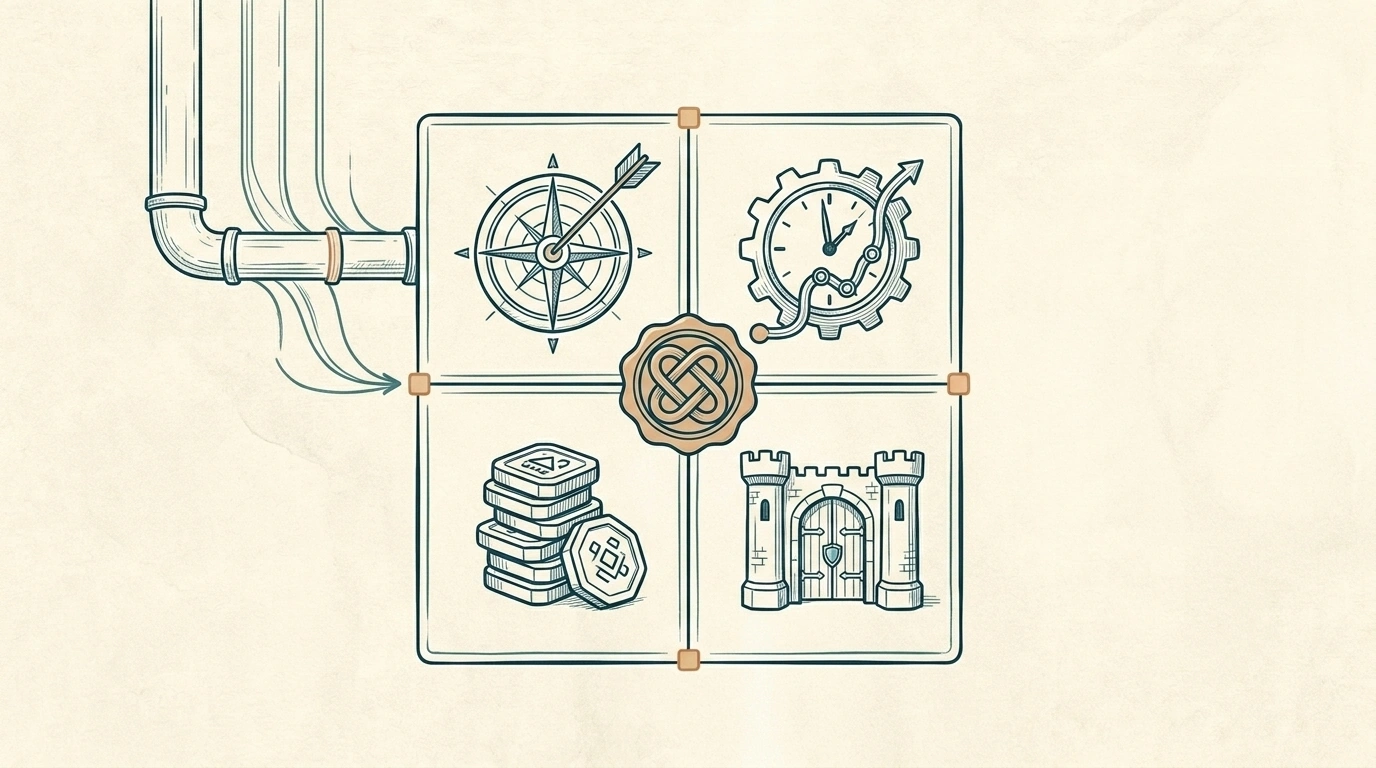
My working model is a four-dimensional scorecard: success, latency, cost, and safety. These dimensions should be measured from the same trace, because a task is only truly healthy when the outcome is useful, arrives within an acceptable time, stays within budget, and does not create an unacceptable risk.
Availability is necessary but not sufficient
Availability answers whether the service responded. It does not answer whether the agent completed the task.
Suppose an agent is asked to reschedule a delivery. It returns a polite confirmation, but the calendar tool timed out and no reservation changed. From an HTTP perspective, the request succeeded. From the user’s perspective, it failed.
The first step is therefore to define a task-level outcome. A task should end with a structured status such as completed, partially_completed, needs_user_input, blocked_by_policy, or failed. The label should be derived from observed state and tool results rather than from the model’s final sentence.
| Dimension | Question | Example SLO signal |
|---|---|---|
| Success | Did the intended task complete correctly? | Valid completed tasks / eligible tasks |
| Latency | Did it complete within the user’s patience budget? | p95 end-to-end duration |
| Cost | Did it stay within the task budget? | p95 cost and budget-exceeded rate |
| Safety | Did it obey policy and avoid harmful side effects? | Safe completions / eligible tasks |
The denominator matters. If blocked requests are excluded from the success calculation, the number may look better while users experience more friction. Define eligibility and exclusions explicitly, and keep them stable enough to compare releases.
Success needs a contract, not a feeling
Success rate is often presented as a single percentage produced by a judge model. That may be useful as one signal, but it is too vague to serve as the only SLO.
For a support agent, success could require that the answer cites the correct order state, that a refund was created with the intended amount, and that no policy violation occurred. For a research agent, success might mean that the final report contains the requested sections and passes a factual review. For an operational agent, the real outcome may be a state transition in another system.
I prefer to define success as a small contract of observable checks:
success =
  task_intent_matched
  AND required_fields_present
  AND tool_result_consistent
  AND expected_state_transition_observed
  AND no_policy_violation
This does not eliminate judgment. Some tasks still require human review or a graded quality score. It does make the agent’s behavior inspectable and allows the team to distinguish “the answer sounded good” from “the workflow completed.”
A regression suite can provide the pre-release version of this contract. The production SLO should then observe the same dimensions on real traffic, with privacy controls around the evidence.
Latency is a budget across stages
End-to-end latency is the number the user feels, but it is not the only number engineers need. An agent’s time is usually divided among routing, retrieval, model calls, tool execution, retries, and human waiting.
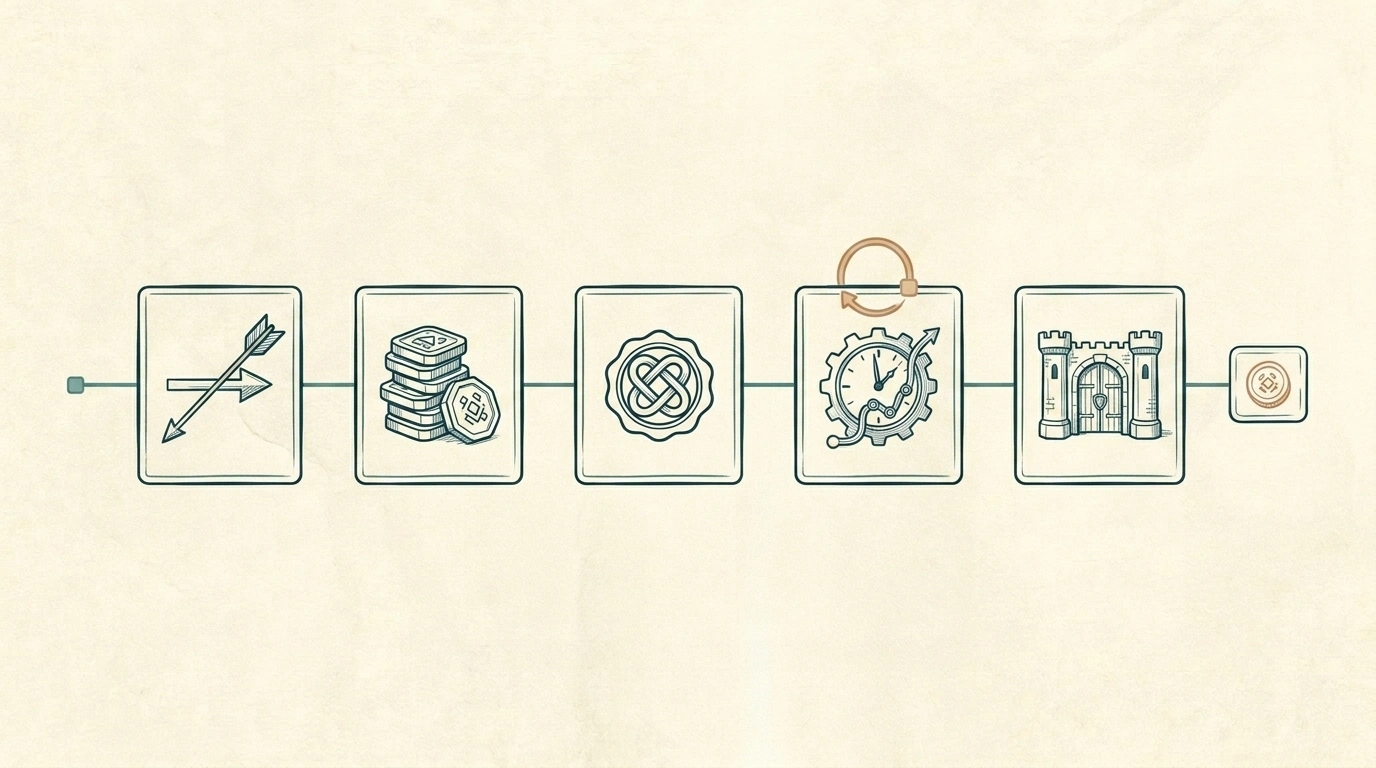
A useful budget might look like this:
| Stage | Budget | What to inspect when it grows |
|---|---|---|
| Initial routing | 300 ms | Model choice, queueing, cold start |
| Retrieval | 800 ms | Index latency, filters, fan-out |
| Reasoning and tool selection | 2 s | Model latency, context size, loops |
| Tool execution | 1.5 s | Downstream API, retries, connection pool |
| Final response | 1 s | Output length, streaming behavior |
The exact numbers depend on the product. The important design choice is to reserve an explicit budget for uncertainty. If the agent can ask a clarifying question, that is not necessarily a latency failure; it may be the safest way to avoid an incorrect action. If the agent silently loops through five tools, it may be both slow and unsafe.
Measure p50 for the normal experience, p95 for the SLO, and a tail indicator such as p99 for runaway behavior. Slice the data by task type, model, tool, tenant, and whether a human gate was involved. An overall p95 can hide a specific workflow that is consistently unusable.
Cost is part of reliability
A task that succeeds but costs ten times more than planned is not operationally healthy. Cost affects whether the system can scale, whether the user receives a predictable experience, and whether a small prompt can trigger an expensive loop.
Track cost at the task level, not only at the model-call level. A task may include input tokens, output tokens, cached context, embedding calls, retrieval operations, tool execution, and retries. The trace should connect those events to one task identifier.
A simple budget policy can combine a soft threshold and a hard threshold. Near the soft threshold, the agent switches to a cheaper model, reduces context, or asks the user to narrow the request. At the hard threshold, it stops and returns a clear partial result rather than continuing an invisible loop.
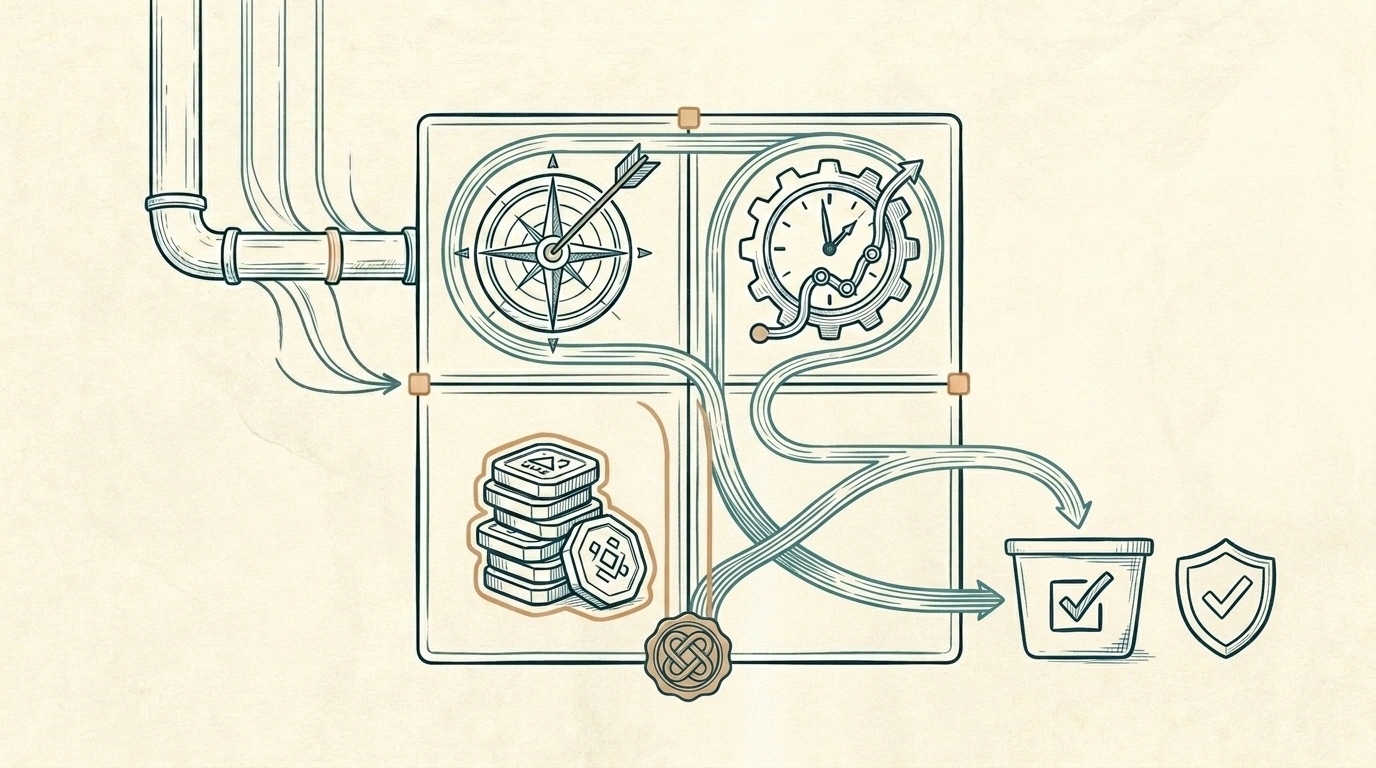
Do not optimize cost by hiding work. If a summarization step is removed and the user receives a lower-quality answer, the success metric should show that trade-off. Cost is a dimension of the SLO because it must be balanced against outcome quality, not minimized in isolation.
Safety needs an error budget too
Safety is often described as a checklist that sits outside reliability engineering. In an agent, safety failures are production failures.
A safety SLO can include policy violations, unauthorized tool calls, sensitive-data exposure, unsafe destinations, failed approval requirements, and actions executed with stale authorization. The exact set depends on the domain, but the principle is consistent: define observable bad outcomes and make them part of release decisions.
Some events should have a zero-tolerance policy. An unauthorized transfer, secret disclosure, or cross-tenant read should not be averaged into a monthly percentage and dismissed as a small error rate. Other events may be measured as a rate, such as the percentage of low-risk tasks that require unnecessary escalation.
Safety telemetry must be designed carefully. The team needs enough structured evidence to investigate, but raw prompts, tool arguments, or customer records should not automatically become searchable logs. The privacy-aware approach in agent observability without data leaks is a useful companion here: record metadata and controlled evidence, not unlimited content.
One trace should connect all four dimensions
The SLO scorecard becomes useful when success, latency, cost, and safety can be joined through one trace.
A root task span can carry the task type, tenant class, model route, outcome status, policy version, and release version. Child spans can represent retrieval, model calls, tool proposals, policy decisions, human approvals, tool execution, and state verification.
For every task, the system should be able to answer:
- What did the user ask the agent to accomplish?
- Which route did the agent take?
- Which tool calls were proposed and which were executed?
- How long did each stage take?
- How much did the task cost?
- Which policy decisions or human gates affected the outcome?
- What external state proves that the task actually completed?
This is more valuable than a dashboard with four unrelated counters. It allows an engineer to see that success fell because a retrieval index slowed down, or that cost increased because a fallback model was invoked after a tool retry, or that safety blocks increased after a policy change.
Alerts should protect the budget, not create noise
A good alert describes a decision the team can make. “Agent quality is down” is not enough. A better alert says that the refund workflow’s completed-task SLO fell below its target for two consecutive windows, while unauthorized-action attempts increased after a new prompt version.
Use burn-rate thinking for error budgets. A fast burn should page the responsible team; a slow burn can create a ticket or trigger a review. Keep separate budgets for availability-like failures, quality failures, cost overruns, and safety events. Combining them into one number makes the remediation path unclear.
Avoid alerting on every model variation. The purpose of an SLO is to protect a user-visible promise, not to punish harmless internal changes. At the same time, preserve enough dimensions to find regressions quickly. A service-level target can be broad while the diagnostic dashboard remains detailed.
A practical starting scorecard
For a first production version, I would start with one task family and define a small scorecard:
| Target | Example objective | Review trigger |
|---|---|---|
| Completed task | At least 95% of eligible tasks complete correctly | Two-window burn above target |
| End-to-end latency | p95 below the user budget | Tail latency grows after a route change |
| Task cost | p95 below the budget with rare hard stops | Budget-exceeded rate rises |
| Safety | Zero unauthorized high-impact actions | Immediate incident review |
The numbers are examples, not universal defaults. The important part is that each target has a clear denominator, an evidence path, and an owner. Start with a narrow workflow, validate the measurement, then expand the scorecard.
An AI agent is not reliable because it sounds confident or because its endpoint stays available. It is reliable when the system can prove that the intended task completed, within a tolerable time and cost, without crossing a safety boundary. SLOs turn that definition into an engineering practice: measurable, reviewable, and difficult to hide behind a single success percentage.
Comments (0)